Inference Interviews
Every token. Every engineering decision.
Focused preparation for inference engineers: model serving, KV memory, GPU kernels, scheduling, numerics and decoding, with the arithmetic shown and experiments you can run.
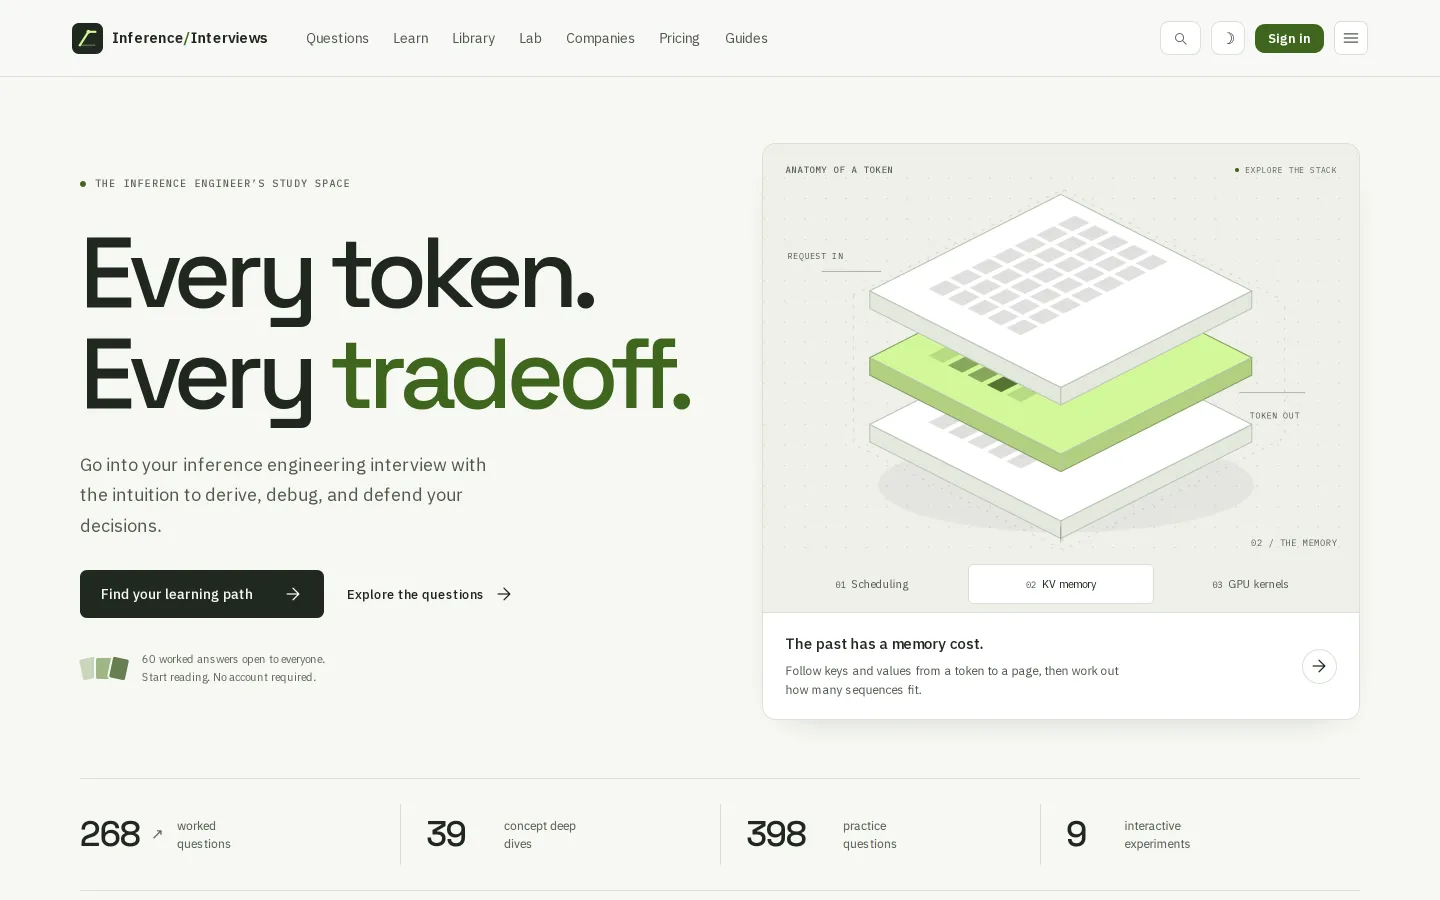
- 268worked interview questions
- 398practice-test items
- 9interactive lab experiments
- 8in-browser code drills
- 4Premium PDF books
- 35company interview guides
Counted from the published library on 9 November 2026.
Who it prepares.
- Inference Engineer
- ML systems and performance engineers
- GPU kernel engineers
- Platform teams running LLM fleets
What it goes deep on.
- Inference & serving
- GPUs & accelerators
- Cloud, Kubernetes & infrastructure
- System design
- Coding
- Evaluation
- Training & fine-tuning
- MLOps, DevOps & SRE
- AI security & safety
A dedicated topic, course or trackCovered within other topics
Explain the bottleneck before choosing an optimization.
Start here when the role centers on the serving path: token latency, memory use, batching, kernels, and engine behavior. For a broader training-cluster or GPU-fleet remit, compare the AI Infra Interviews curriculum too.
Finish with a benchmark plan and an assumptions table. Separate an analytical estimate from a measured result so another engineer can reproduce the comparison.
Try it before reading the answer.
- 1. Define the workload: prompt and output lengths, concurrency, hardware, and the latency or throughput target.
- 2. Work through speculative decoding with both draft and verification costs. State which measurements would make you turn it off.
- 3. Describe the benchmark that could disprove your recommendation, including tail latency and resource use under matched load.
Work through speculative decoding
Free concept on Inference Interviews. Access follows the destination platform's rules.
Every token. Every tradeoff.
A look at what you work with on inferenceinterviews.com.
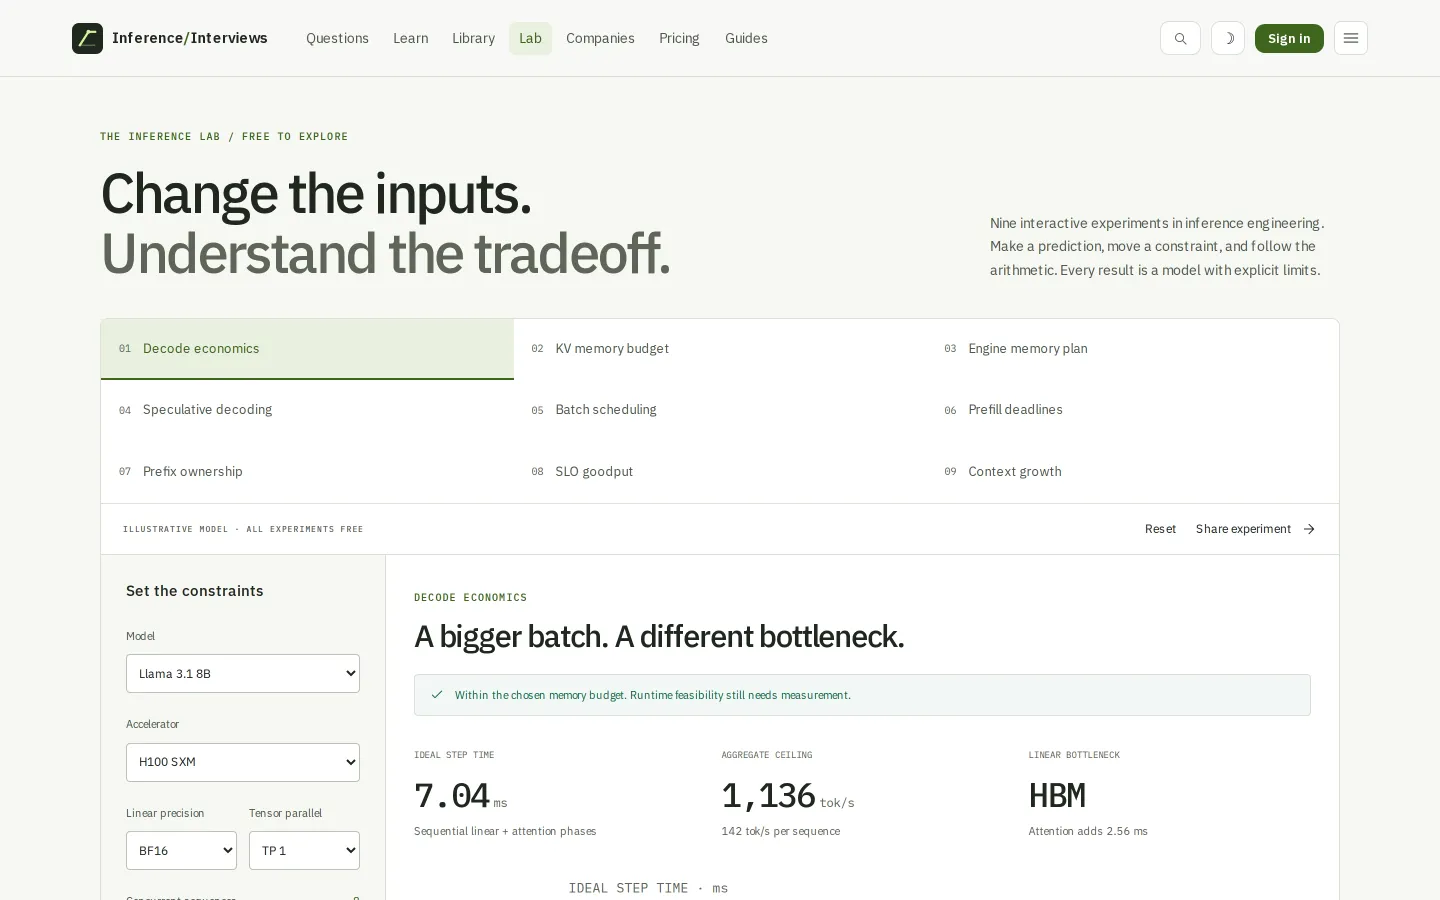
The inference lab: change the inputs and watch the bottleneck move
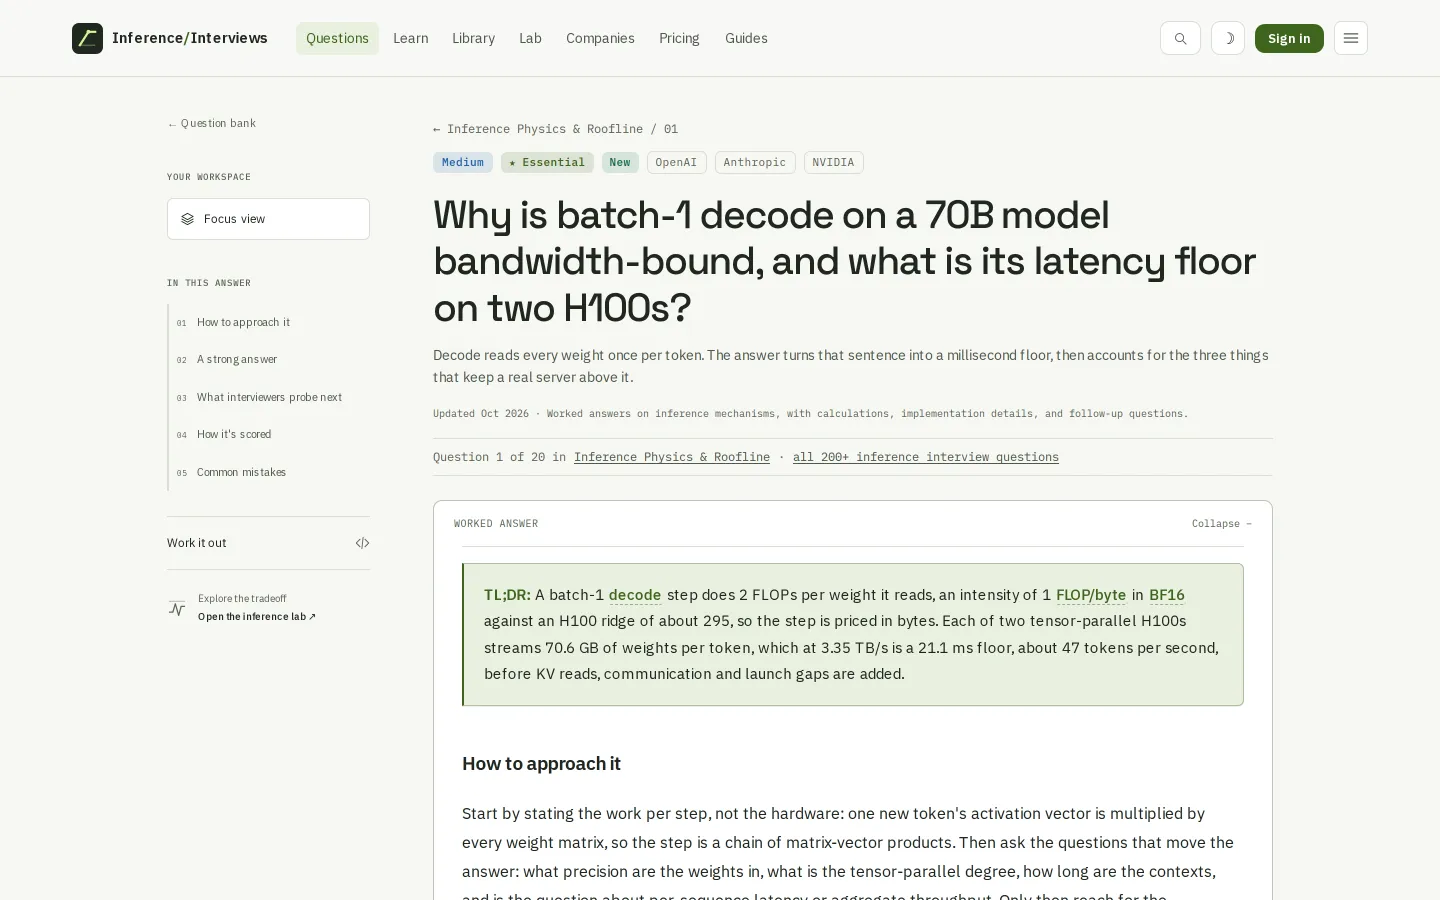
A worked answer: the latency floor of batch-1 decode for a 70B model
12 interview topics
- Inference physics & roofline
- KV cache & GPU memory
- Batching, scheduling & admission
- Attention kernels
- CUDA, Triton & GPU performance
- Quantization & numerics
- Speculative & constrained decoding
- Distributed & disaggregated inference
- Serving engine internals
- Inference system design
- Performance debugging & benchmarking
- Implement-from-scratch coding
What Premium unlocks.
- Every answer across all 12 topics, warm-up to staff level
- Reference solutions and edge-case tests for all 8 code drills
- All 39 concept pages and all 18 course lessons
- Practice tests at every difficulty, including adaptive runs
- The inference field guide as a PDF
Free answers and lessons in every topic stay free. Premium opens the rest.
7 more platforms.
- FDE InterviewsForward deployed engineering
- AI Infra InterviewsThe infrastructure behind intelligence
- Applied AI PrepFrom models to meaningful products
- DevOps Interview PrepEngineering that keeps the world running
- AI Interview TrainingA foundation for the AI era
- AI PM InterviewsProduct judgment for the AI era
- AI Security InterviewsProtecting the systems we build.